
Home / Use cases / AI stem separation engine
MEDIA & ENTERTAINMENT
MUSIC TECH
AI & AUDIO
API PLATFORM
AI stem separation engine for music-tech companies
Clean stems from finished songs, served by API to producers and partner apps. Custom source separation models, autoscaling GPU serving, and a web app and API for creators and partners.
Example engagement: figures show typical results for this kind of project.
6
stems: vocals, drums, bass, piano, guitar, other
9 mo
typical timeline, phased
8
services working together
3
user roles, each with its own workspace
BUILT FOR
Music-tech companies and audio platforms
INDUSTRY
Media & Entertainment
TYPICAL SIZE
Growth stage
WHERE WE DELIVER
United States, Canada and Europe
TYPICAL TIMELINE
9 months, phased
TEAM
Cross-practice: AI and data, software, managed cloud, security
Services used:
Machine learning
MLOps & LLMOps
API & integration
Web applications
Data engineering
Cloud cost optimization
Managed cloud
Cloud & app security
IN SHORT
What is AI stem separation and how is it used in music?
AI stem separation splits a finished song into its parts, such as vocals, drums, bass and piano, using deep learning models. Labels, producers and apps use it for remixes, karaoke, sync licensing, remastering and catalogue reuse. Quality is measured with signal-to-distortion ratio (SDR).
KEY TAKEAWAYS
→ Measure separation quality per stem with SDR on a fixed test set
→ Ship new models only when they beat production on that set
→ Use GPU batching and spot capacity to cut cost per minute
→ Keep customer audio private: no training on uploaded tracks without consent
THE CHALLENGE
Great idea, hard engineering
Music-tech teams often have strong research, but customers need studio quality, speed and an API they can build on.
01
Quality not good enough for pros
Early models left drum bleed in vocals and smeared piano and guitar, so producers rejected the stems.
02
Too slow and too expensive
Separating a song took several minutes on dedicated GPUs, making large catalogue jobs unaffordable.
03
No product around the model
Without a creator studio, a stable API and partner tooling, the technology can't scale into a product.
TECHNICAL ARCHITECTURE
From uploaded mix to aligned stems
An API-first platform: the creator studio and partners use the same API, and a GPU pipeline scales separation jobs on demand.
USERS
Producers & creators
Creator studio
Developers & partners
REST API & SDKs
Operations
Pipeline dashboard
Catalogue clients
Batch jobs
↓
ACCESS
SSO & roles
API gateway
Usage metering
Keys, quotas, billing
↓
SEPARATION PIPELINE
Upload & decode
Loudness & format checks
6-stem model
GPU inference
Vocal clean-up
De-reverb, de-bleed
Alignment & export
↓
QUALITY
Evaluation service
SDR on a held-out test set
A/B model rollout
Listening panel
↓
DATA
Object storage
Encrypted, auto-expiry
Job metadata
Usage & billing
Audit logs
↓
INTEGRATIONS
DAW export
Webhooks
Catalogue systems
Payments
SECURITY & RIGHTS
Across every layer
• Uploads encrypted and auto-deleted after 30 days
• No training on customer audio without consent
• Signed webhooks (HMAC)
• Per-key scopes and quotas
• Content hashing to detect repeat uploads
• Region choice for EU customers
• Penetration tested before launch
• SOC 2-aligned controls
THE SOLUTION IN DETAIL
One engine, three experiences
Creators get studio-quality stems in seconds, developers get a reliable API, and operations keep quality up and costs down.
Product screens on this page show the design with sample data.
01
Producers & creators
Separation studio
6 core features
02
Developers & partners
Stem separation API
6 core modules
03
Operations & quality
GPU pipeline dashboard
6 core modules
01
SEPARATION STUDIO
Producers & creators
Creators upload a mix, choose a model and get six aligned stems with quality scores, ready to drop into any DAW.
CORE FEATURES
✓
Drag-and-drop upload
WAV, FLAC, AIFF or MP3, up to 20 minutes at 24-bit / 96 kHz.
✓
2, 4 or 6 stems
Vocals, drums, bass, piano, guitar and other, at fast or high quality.
✓
Quality score per stem
SDR shown for every stem, so users know what to expect.
✓
Vocal clean-up
Optional de-reverb and de-bleed for cleaner a cappellas.
✓
Mute, solo and preview
Audition every stem in the browser before exporting.
✓
Export to DAW
Sample-aligned 24-bit WAV stems, named and ready for Ableton or Logic.
S
Stem Studio
CREATOR
Library
Separation studio
Exports
Projects
Settings
Separation studio
Midnight Drive.wav · 3:42 · 44.1 kHz stereo
Search tracks, jobs…
Input mix
Separated in 38 s
Model: 6-stem · High quality
Loudness −9.8 LUFS
Key A minor · 118 BPM
Separation quality
Vocals
SDR 9.4 dB
Drums
SDR 8.9 dB
Bass
SDR 8.1 dB
Piano
SDR 6.7 dB
Stems
6 stems
Vocals
Lead + backing
M
S
0 dB
Drums
Stereo · 24-bit
M
S
0 dB
Bass
Stereo · 24-bit
M
S
0 dB
Piano
Stereo · 24-bit
M
S
0 dB
Guitar
Stereo · 24-bit
M
S
0 dB
Other
Stereo · 24-bit
M
S
−18 dB
Export stems to DAW
Re-run with vocal clean-up
Share preview link
Separation studio: six aligned stems with quality scores
S
Stem Studio
CREATOR
Library
Separation studio
Exports
Projects
Settings
New separation
Upload a mix and choose how to split it
Search tracks, jobs…
Upload
Drop WAV, FLAC, AIFF or MP3
Up to 20 minutes · 24-bit / 96 kHz supported
Midnight Drive.wav
48.2 MB · uploaded
Ready
Choose model
2 stems
Vocals + instrumental · fastest
4 stems
Vocals, drums, bass, other
6 stems
Adds piano and guitar · recommended
Vocal clean-up
Removes reverb and bleed from vocals
Fast
Balanced
High quality
Start separation →
Upload and choose a model
S
Stem Studio
CREATOR
Library
Separation studio
Exports
Projects
Settings
Export stems
Midnight Drive · 6 stems
Search tracks, jobs…
Format
File type
WAV, 24-bit
Sample rate
48 kHz (match session)
Alignment
Sample-accurate, same start point
Naming
Track_Stem_BPM_Key.wav
Stems in this export
Stem
Peak
Size
Status
Vocals
−1.2 dB
42 MB
Ready
Drums
−0.8 dB
42 MB
Ready
Bass
−3.1 dB
42 MB
Ready
Piano
−6.4 dB
42 MB
Ready
Guitar
−5.0 dB
42 MB
Ready
Other
−9.7 dB
42 MB
Ready
Download ZIP · 252 MB
Send to Ableton Live
Send to Logic Pro
Export sample-aligned stems to a DAW
02
STEM SEPARATION API
Developers & partners
Partners integrate separation into their apps and catalogue tools with a REST API, SDKs, webhooks and clear usage billing.
S
Stem API
DEVELOPER
Overview
Jobs
API keys
Webhooks
Usage & billing
Docs
API overview
Production · last 30 days
Search tracks, jobs…
Minutes separated
1.24M
+18%
Median job time
0.21× real time
faster
Success rate
99.94%
SLA 99.9%
p95 API latency
182 ms
Recent jobs
Job
Track
Stems
Duration
Status
job_8f21
catalog_00412.wav
6
3:42
Done
job_8f20
demo_vox_v3.flac
2
2:58
Done
job_8f1f
live_set_09.wav
4
18:40
Processing
job_8f1e
podcast_ep55.mp3
2
42:10
Queued
job_8f1d
remix_pack_a.wav
6
4:05
Done
POST /v1/separations
{
"audio_url": "s3://catalog/…/track.wav",
"model": "6-stem-hq",
"output": "wav_24bit_48k",
"webhook": "https://…/stems-ready"
}
→ 202 Accepted · job_8f21
Minutes processed per day
API overview: jobs, latency and minutes processed
S
Stem API
DEVELOPER
Overview
Jobs
API keys
Webhooks
Usage & billing
Docs
Webhooks & API keys
Secure delivery of finished stems
Search tracks, jobs…
API keys
Name
Scope
Created
Last used
Status
catalog-batch
separations:write
12 Mar 2026
2 min ago
Active
mobile-app
separations:read
02 Apr 2026
1 h ago
Active
legacy-test
all
10 Jan 2026
45 days ago
Rotate
Webhooks
stems.ready → https://catalog.internal/hooks
Signed with HMAC-SHA256 · 99.98% delivered
job.failed → PagerDuty
3 failures in 30 days, all retried
Webhooks and scoped API keys
S
Stem API
DEVELOPER
Overview
Jobs
API keys
Webhooks
Usage & billing
Docs
Usage & billing
November 2026
Search tracks, jobs…
Minutes this month
412,880
Committed
500,000
Cost per minute
$0.0042
−31%
Forecast
96% of plan
Usage by model
6-stem high quality
58%
4-stem
24%
2-stem fast
12%
Vocal clean-up
6%
Usage and billing by model
CORE FEATURES
✓
REST API and SDKs
One call to submit a track, with Python and Node.js SDKs.
✓
Asynchronous jobs
Jobs queue instantly and report status in real time.
✓
Signed webhooks
Stems-ready events signed with HMAC for safe delivery.
✓
Scoped API keys
Per-key scopes, quotas and rotation reminders.
✓
Usage and billing
Minutes by model, committed plans and forecasts.
✓
Sandbox
Free test tracks and a sandbox environment for integration.
03
GPU PIPELINE DASHBOARD
Operations & quality
The operations team runs a multi-region GPU pipeline, tracks quality on every model release and keeps cost per minute falling.
CORE FEATURES
✓
Queue and throughput
Live jobs, queue time and audio hours per hour by region.
✓
GPU autoscaling
Scales on queue depth with spot capacity and on-demand fallback.
✓
Model evaluation
Every candidate model scored on a fixed, held-out test set.
✓
Safe rollouts
A/B releases with automatic rollback if quality drops.
✓
Cost per minute
Cost tracked per model, region and customer.
✓
Incident alerts
Paging for failed jobs, spot reclaims and latency spikes.
S
Stem Ops
OPERATIONS
Pipeline
Quality
Models
Costs
Incidents
GPU pipeline
Live · 3 regions
Search tracks, jobs…
Jobs in queue
214
normal
GPU utilisation
81%
+9 pts
Cost per audio minute
$0.0042
−31%
Median SDR (vocals)
9.4 dB
+1.1 dB
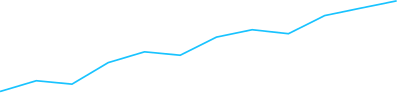
Throughput (audio hours per hour)
Alerts
Spot capacity reclaimed in us-east
Jobs moved to on-demand in 40 s
Vocal SDR drift check passed
Weekly evaluation on 1,000 tracks
Queue under 2 min
All regions
Regions
Region
GPUs
Utilisation
Queue
Status
us-east
48 · L4 + spot
84%
92 jobs
Healthy
eu-west
32 · L4
79%
71 jobs
Healthy
ap-south
16 · L4
76%
51 jobs
Healthy
GPU pipeline: queue, throughput and alerts
S
Stem Ops
OPERATIONS
Pipeline
Quality
Models
Costs
Incidents
Model evaluation
Candidate v4.2 vs production v4.1 · 1,000-track test set
Search tracks, jobs…
Signal-to-distortion ratio (SDR, dB) by stem
Stem
v4.1 (prod)
v4.2 (candidate)
Change
Decision
Vocals
8.9
9.4
+0.5
Ship
Drums
8.6
8.9
+0.3
Ship
Bass
8.0
8.1
+0.1
Ship
Piano
6.1
6.7
+0.6
Ship
Guitar
5.8
5.7
−0.1
Watch
Model evaluation before every release
S
Stem Ops
OPERATIONS
Pipeline
Quality
Models
Costs
Incidents
Cost per audio minute
Last 12 weeks
Search tracks, jobs…
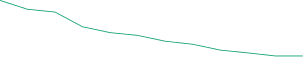
Cost per minute (USD)
Savings levers
Spot GPUs with checkpointing
42% of savings
Batching short tracks
27%
FP16 + TensorRT inference
21%
Caching repeat uploads
10%
Cost per audio minute, down 31%
TECHNOLOGY & SECURITY
Built for audio quality, speed and scale
PyTorch models served on GPUs with TensorRT, an API-first platform and a pipeline that scales across three regions.
TECHNOLOGY STACK
Audio & ML
PyTorch
Source separation models
TensorRT
Serving
GPU workers (L4)
Spot capacity
Job queue
Product
Next.js studio
Web Audio API
REST API & SDKs
Data
Object storage
PostgreSQL
Evaluation sets
Cloud
AWS (3 regions)
Kubernetes
Terraform
Operations
Prometheus & Grafana
PagerDuty
Cost dashboards
SECURITY & COMPLIANCE
✓ Uploads encrypted in transit and at rest
✓ Customer audio auto-deleted after 30 days
✓ No training on customer audio without consent
✓ Signed webhooks and scoped API keys
✓ Regional processing for EU customers
✓ Penetration tested before launch
✓ SOC 2-aligned access and logging controls
✓ Content hashing to stop abusive re-uploads
DELIVERY TIMELINE
From research model to production platform in about 9 months
A creator beta proves quality early; the API and scale-out follow.
Month 0
Month 1
Month 3
Month 4
Month 5
Month 6
Month 8
Month 9
Discovery & evaluation set
Benchmarks and a held-out test set.
Wk 0–4
Model improvement
6-stem model and vocal clean-up.
Wk 3–16
Creator studio
Upload, preview, export to DAW.
Wk 6–18
API & SDKs
Jobs, webhooks, keys, billing.
Wk 12–26
GPU pipeline at scale
Autoscaling, spot, 3 regions.
Wk 16–30
Partner beta & launch
Partner integrations, public launch.
Wk 26–34
Cost & quality tuning
Batching, TensorRT, rollouts.
Wk 30–39
Typical plan: about 9 months to a production platform · creator beta first
Studio-grade stems at a predictable cost per audio minute, for creators and partner apps. Custom source separation models, autoscaling GPU serving, and a web app and API for creators and partners.
WHAT THIS USE CASE DELIVERS
Use case blueprint. Scope, timeline and team are confirmed in a written proposal for your project.
RELATED USE CASES
More media and music work
MEDIA
Audio AI
AI governance
Vocal intelligence and AI voice clone detection for music companies
THE CHALLENGE
AI clones of artists' voices spread faster than rights teams can find, prove and remove them.
OUR APPROACH
Vocal fingerprints for every recording, clone detection across platforms and evidence-ready takedowns with audit trails.
WHAT SUCCESS LOOKS LIKE
Clones found and removed faster, with a chain of custody that stands up to platforms and counsel.
3
teams: A&R, rights & legal, platform admin
Read the story →
1 / 3
RELATED INDUSTRIES
Built for your industry
The industry behind this use case, and others where the same approach works.
All industries →
BLOG & RESOURCES
Insights for media and entertainment leaders
Practical guides on catalog data, AI and content security.
View all resources →
MEDIA & AI
Generative AI on your catalog, with consent and rights intact
A 6-step plan for labels, publishers and broadcasters.
Akash Soni, Founder & CEO · 9 min read
MEDIA & DATA
Music metadata and royalties: how splits decide what you get paid
ISRC, ISWC, IPI and a plan to recover unmatched royalties.
Akash Soni, Founder & CEO · 9 min read
FINOPS
Cloud cost optimization: 10 quick wins
Right-sizing, tagging and reserved capacity for busy teams.
Krima Soni, CFO · 8 min read
FAQ
AI stem separation questions, answered
Short answers to what teams ask us most about this kind of project.

Still have a question?
Book a free consultation

What is AI stem separation?
AI stem separation splits a finished song into its parts, such as vocals, drums, bass, piano and other instruments, using neural networks trained on multitrack recordings. Producers use the stems for remixes, karaoke, sampling, mix fixes and sync licensing, without needing the original session files.
How is stem separation quality measured?
Quality is usually measured with signal-to-distortion ratio (SDR) on a held-out test set, reported for each stem. We pair SDR with blind listening tests by audio engineers, because a higher number does not always mean fewer audible artefacts such as bleed, phasing or smeared transients.
How long does it take to build a custom stem separation engine?
A production-ready engine typically takes 10 to 16 weeks: data and rights review, model training and evaluation, GPU serving, then an API and web app. A pilot on one genre or stem type can show measurable quality gains within the first 4 to 6 weeks.
How do you keep GPU costs under control for audio AI?
We batch requests, autoscale GPU workers to the queue, use mixed precision and smaller models where quality allows, and cache results for repeat files.
Can stem separation models be trained on licensed music only?
Yes. We train and fine-tune only on multitrack audio the client owns or has licensed, keep a record of every dataset used, and exclude content without clear rights. This protects the business with labels and artists and makes AI governance reviews and audits straightforward.
RELATED SERVICES
Machine Learning & Predictive Analytics →
Forecasts and models your team can trust
MLOps & LLMOps Services →
Run models in production at a known cost
API & Systems Integration →
Connect every system you run
Web Application Development →
Fast, secure web apps
Need cleaner stems at a lower cost? Let's talk.
Book a free 30-minute call. You'll leave with a model and serving plan for your audio.

A quality benchmark plan
A cost per minute estimate
No obligation