
Home / Use cases / GPU FinOps and 24/7 managed cloud
SAAS & TECHNOLOGY
STARTUP
FINOPS
24/7 MANAGED CLOUD
GPU FinOps and 24/7 managed cloud for voice AI startups
Autoscaled GPU fleet, on-call SRE and unit economics investors can trust. GPU FinOps, smarter autoscaling and 24/7 managed cloud with SRE on call.
Example engagement: figures show typical results for this kind of project.
24/7
SRE and security monitoring
16 wks
typical timeline, then managed
7
services working together
3
user roles, each with its own workspace
BUILT FOR
AI startups running GPU workloads
INDUSTRY
SaaS & Technology
STAGE
Series A, 22 people
WHERE WE DELIVER
United States, Canada and Europe
TYPICAL TIMELINE
16 weeks, then managed
TEAM
Cross-practice: managed cloud, AI and data, software, security
Services used:
Managed cloud services
Cloud cost optimization
SOC as a Service
Backup & DR
MLOps & LLMOps
QA & DevOps
SOC 2 compliance
IN SHORT
How can AI startups reduce GPU and cloud costs without hurting performance?
By matching GPU capacity to real demand and paying less for every unit.
KEY TAKEAWAYS
→ Scale inference GPUs on queue depth, not CPU or schedules
→ Run training and batch jobs on spot with checkpointing
→ Optimise models before buying more GPUs
→ Commit only to steady-state usage; keep peaks on demand
THE CHALLENGE
Sound familiar?
Customers love the product. The cloud bill and the 3 a.m. pages are the problem.
01
A GPU bill growing faster than revenue
GPU spend grows faster than revenue while GPUs sit under-used, and gross margin worries investors.
02
Launches broke the platform
Customer campaigns caused GPU shortages, dropped calls and latency spikes, with engineers paged at night.
03
No time for operations
A small engineering team builds product and runs infrastructure, with no on-call rota or SOC 2 controls.
TECHNICAL ARCHITECTURE
A real-time voice platform, run 24/7
Stateless gateways, GPU pools per model, queue-based autoscaling and cost visibility per customer.
CLIENTS
Customer apps
Web & mobile SDKs
Telephony
SIP & phone numbers
Developer API
REST & WebSocket
↓
EDGE
Global edge
Low-latency routing
Voice gateway
WebRTC & WebSocket
Auth & rate limits
↓
INFERENCE
Speech recognition pool
L4 GPUs
LLM reasoning pool
H100 GPUs
Text-to-speech pool
L4 GPUs
Queue-based autoscaler
Warm pools
↓
BATCH & TRAINING
Fine-tuning jobs
Spot GPUs
Evaluation jobs
Model registry
↓
DATA
Usage & billing DB
Call recordings
Customer opt-in, encrypted
Metrics & traces
Cost data
Tagged per customer
↓
OPERATIONS
Kubernetes
Observability
Incident management
FinOps dashboards
OPERATIONS & SECURITY
Across every layer
• 24/7 SRE on-call with SLOs
• Queue-depth GPU autoscaling
• Warm pools for launch peaks
• Spot with checkpointing for batch
• Cost allocation per customer
• SOC 2 controls and evidence
• Daily backups, tested restores
• Security monitoring 24/7
THE SOLUTION IN DETAIL
One platform, three types of users
Engineers see cost and performance, Zuroth SRE keeps it running, and founders see the unit economics.
Product screens on this page show the design with sample data.
01
Engineering team
Cost & performance
6 core modules
02
24/7 operations
Service health
6 core modules
03
Founders & finance
Unit economics
6 core modules
01
COST & PERFORMANCE
Engineering team
Engineers see spend, GPU utilisation and latency side by side, so every product decision includes its cost.
CORE MODULES
✓
Spend by service
Tagged, allocated and explained.
✓
GPU utilisation
Per pool, per model, per hour.
✓
Latency SLOs
p50 and p95 end-to-end voice latency.
✓
Savings tracker
Every optimisation and its monthly value.
✓
Model optimisation
Distillation and quantisation results.
✓
Cost per customer
Usage-based allocation for pricing.
V
Voxa AI
ENGINEERING
Spend
GPUs
Latency
Commitments
Cloud & GPU spend
October · all environments · tagged 99%
Search services, clusters, incidents…
Monthly cloud spend
$98.4k
−45%
GPU share of spend
71%
Cost per audio minute
$0.0061
−58%
Untagged spend
0.8%
Monthly spend (USD thousands)
Mar
Apr
May
Jun
Jul
Aug
Sep
Oct
Savings delivered
GPU autoscaling & bin-packing
$31k / mo
Spot for batch & training
$22k / mo
Model distillation & quantisation
$17k / mo
Savings plans
$11k / mo
Cloud & GPU spend
V
Voxa AI
ENGINEERING
Spend
GPUs
Latency
Commitments
GPU fleet
Inference on H100 and L4 pools · autoscaled on queue depth
Search services, clusters, incidents…
Average GPU utilisation
78%
was 31%
GPUs at peak
212
GPUs at night
38
Spot for batch jobs
84%
GPUs in use over 24 hours
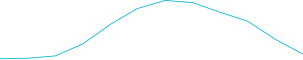
GPU fleet utilisation
V
Voxa AI
ENGINEERING
Spend
GPUs
Latency
Commitments
Real-time voice latency
Speech-to-speech round trip · measured at the edge
Search services, clusters, incidents…
p50 latency
310 ms
p95 latency
620 ms
−41%
Streams at peak
18,400
Error rate
0.03%
p95 latency by week (ms)
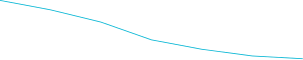
Real-time voice latency
02
SERVICE HEALTH
24/7 operations
Zuroth SRE runs on-call around the clock, scales ahead of known peaks and reviews every serious incident with the founders.
V
Voxa AI
24/7 OPERATIONS
Health
Incidents
Scaling
Security
Service health
Managed by Zuroth SRE · 24/7 on-call
Search services, clusters, incidents…
Uptime (30 days)
99.97%
Active incidents
0
SLO error budget left
82%
Mean time to restore
14 min
Services
SERVICE
REGION
LATENCY P95
ERROR RATE
REPLICAS
STATUS
Voice gateway
US-East, EU-West
42 ms
0.01%
24
Healthy
Speech recognition
US-East, EU-West
180 ms
0.02%
64 GPUs
Healthy
LLM reasoning
US-East
240 ms
0.04%
96 GPUs
Healthy
Text-to-speech
US-East, EU-West
150 ms
0.02%
52 GPUs
Healthy
Billing & usage
US-East
80 ms
0.00%
6
Healthy
Service health
V
Voxa AI
24/7 OPERATIONS
Health
Incidents
Scaling
Security
Incidents
Post-incident reviews for every Sev 1 and Sev 2
Search services, clusters, incidents…
Last 90 days
INCIDENT
SUMMARY
SEVERITY
DETECTED
RESTORED
REVIEW
INC-212
GPU node pool exhausted during launch
Sev 2
Auto · 1 min
9 min
Done
INC-207
Upstream model API rate limit
Sev 3
Auto · 2 min
6 min
Done
INC-198
Certificate renewal on EU gateway
Sev 3
Auto · 1 min
4 min
Done
Incidents and reviews
V
Voxa AI
24/7 OPERATIONS
Health
Incidents
Scaling
Security
Autoscaling
Queue-depth based scaling with warm pools
Search services, clusters, incidents…
Today
08:02 · Scaled up 38 → 120 GPUs
US morning peak, warm pool used, 0 dropped streams
13:30 · Scaled up 120 → 212 GPUs
Customer campaign launch, pre-scaled from forecast
22:10 · Scaled down 176 → 52 GPUs
Spot nodes released, batch jobs resumed
02:00 · Nightly fine-tuning on spot
84% spot, checkpointing every 10 min
Autoscaling events
CORE MODULES
✓
Service health
SLOs and error budgets per service.
✓
Incident management
Detect, respond, review.
✓
Autoscaling
Queue-based scaling with warm pools.
✓
Launch readiness
Pre-scaling from customer campaign calendars.
✓
Backups & DR
Daily backups and quarterly restore tests.
✓
Security monitoring
24/7 alerting and response.
03
UNIT ECONOMICS
Founders & finance
Founders see gross margin, cost per minute and runway impact in the same view they share with investors.
CORE MODULES
✓
Gross margin
By product and by month.
✓
Cost per minute
Infrastructure cost per audio minute.
✓
Spend forecast
Six months ahead, driven by usage.
✓
Commitments
Savings plans and reservations sized safely.
✓
Credits tracker
Cloud credits and expiry dates.
✓
Board reporting
Margin and reliability in one pack.
V
Voxa AI
FOUNDERS & FINANCE
Unit economics
Forecast
Commitments
Unit economics
Gross margin by product · investor view
Search services, clusters, incidents…
Gross margin
68%
was 31%
Infra cost per minute
$0.0061
Revenue per minute
$0.019
Runway impact
+7 months
Gross margin by month
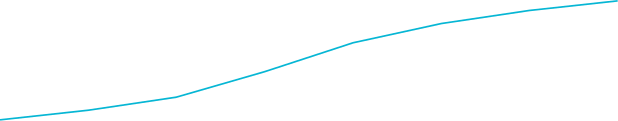
Unit economics
V
Voxa AI
FOUNDERS & FINANCE
Unit economics
Forecast
Commitments
Spend forecast
Next 6 months · usage-driven model
Search services, clusters, incidents…
Forecast vs budget (USD thousands)
Nov
Dec
Jan
Feb
Mar
Apr
Spend forecast
V
Voxa AI
FOUNDERS & FINANCE
Unit economics
Forecast
Commitments
Commitments & credits
Savings plans sized to steady-state usage
Search services, clusters, incidents…
Portfolio
COMMITMENT
TERM
COVERAGE
UTILISATION
MONTHLY SAVING
STATUS
Compute savings plan
1 year
62% of steady compute
98%
$11.2k
Active
GPU capacity reservation
6 months
38 baseline GPUs
96%
$8.4k
Active
Startup cloud credits
Expires Mar
—
—
$40k left
Tracking
Commitments & credits
TECHNOLOGY & SECURITY
Built for real-time AI at startup cost
Kubernetes-based GPU pools with autoscaling, observability and FinOps from day one.
TECHNOLOGY STACK
Compute
Kubernetes
H100 & L4 GPUs
Spot instances
Inference
Model server
Quantisation
Distillation
Scaling
Queue-based autoscaler
Warm pools
Observability
Prometheus
Grafana
OpenTelemetry
FinOps
Cost allocation tags
Savings plans
Budgets & alerts
Cloud
AWS
Terraform
GitHub Actions
SECURITY & COMPLIANCE
✓ SOC 2 controls implemented and evidenced
✓ Encrypted call recordings, customer opt-in only
✓ Least-privilege access with MFA
✓ 24/7 security monitoring
✓ Daily backups and quarterly restore tests
✓ Infrastructure as code for every change
✓ Incident reviews for every Sev 1 and Sev 2
✓ Data residency options for EU customers
DELIVERY TIMELINE
From firefighting to managed in about 16 weeks
Quick savings first, then reliability, then a managed service the founders could forget about.
Month 0
Month 1
Month 2
Month 3
Month 4
Cost & reliability assessment
Spend, utilisation, incidents, quick wins.
Wk 0–2
Quick-win savings
Idle GPUs, rightsizing, storage tiers.
Wk 1–4
GPU autoscaling & warm pools
Queue-based scaling, bin-packing.
Wk 3–9
Spot for batch & training
Checkpointing, scheduling.
Wk 5–10
Model optimisation
Distillation and quantisation with evals.
Wk 6–13
Observability & on-call
SLOs, alerts, runbooks, 24/7 rota.
Wk 4–12
Commitments & managed run
Savings plans, monthly FinOps reviews.
Wk 12–16
Typical plan: about 16 weeks to a managed, cost-efficient platform
Lower cost per request, steady latency and a team that sleeps at night. GPU FinOps, smarter autoscaling and 24/7 managed cloud with SRE on call.
WHAT THIS USE CASE DELIVERS
Use case blueprint. Scope, timeline and team are confirmed in a written proposal for your project.
RELATED USE CASES
More work like this
SAAS
AI agents
SOC 2
Enterprise-ready AI agent with SOC 2 and ISO 42001 for AI startups
THE CHALLENGE
Enterprise legal teams like AI demos, then ask hard security and AI questions.
OUR APPROACH
An evaluation-gated AI agent, SOC 2 and ISO 42001 controls, and a self-serve trust center.
WHAT SUCCESS LOOKS LIKE
An AI product that answers security and AI reviews with evidence, not promises.
3
frameworks built in: SOC 2, ISO 42001, trust center
Read the story →
1 / 3
RELATED INDUSTRIES
Built for your industry
The industry behind this use case, and others where the same approach works.
All industries →
BLOG & RESOURCES
Insights for SaaS and technology leaders
Practical guides on compliance, AI features and scaling your platform.
View all resources →
FINOPS
Cloud cost optimization: 10 quick wins
Right-sizing, tagging and reserved capacity for busy teams.
Krima Soni, CFO · 8 min read
MANAGED SECURITY
SOC as a Service vs MDR vs MSSP: which fits?
What each monitors, who responds and how to choose.
Akash Soni, Founder & CEO · 8 min read
GENERATIVE AI
RAG vs fine-tuning: which one, and what each costs
When retrieval is enough and when to fine-tune.
Akash Soni, Founder & CEO · 8 min read
FAQ
GPU cost and managed cloud questions, answered
Short answers to what teams ask us most about this kind of project.

Still have a question?
Book a free consultation

Why are GPU costs so high for AI startups?
GPUs are expensive and often over-provisioned, sit idle between requests, run large models for simple tasks and lack autoscaling. Without FinOps, GPU spend can grow faster than revenue.
How do you autoscale GPUs for real-time AI?
We scale inference on queue depth and latency, keep a small warm pool, batch requests and use fast model loading, so capacity follows demand without slowing responses.
Is spot capacity safe for AI workloads?
Yes for interruptible work like batch processing and training with checkpoints, and for a share of inference with fallback to on-demand capacity. It can cut compute costs significantly.
What is FinOps?
FinOps is the practice of managing cloud spending through shared visibility, team ownership and decisions based on unit economics, such as cost per customer or per AI request.
Should a startup outsource cloud operations?
Often yes. A managed cloud and SRE partner gives 24/7 coverage and senior expertise for less than hiring a full team, letting engineers focus on the product.
SERVICES IN THIS USE CASE
Managed Cloud Services (AWS, Azure, GCP) →
Resilient cloud, run 24/7
Cloud Cost Optimization & FinOps →
Cut cloud spend without slowing down
24/7 Security Monitoring (SOC as a Service) →
Round-the-clock monitoring of every log
Backup & Disaster Recovery →
Recover in hours, not days
Is your cloud bill growing faster than revenue? Let's talk.
Book a free 30-minute call. You'll leave with your top three savings and what 24/7 operations would cost, whether or not we work together.

Your top three savings
The cost of 24/7 operations
No obligation